How We Annotate and QA So You Can Trust Every Label

TLDR. Every label you receive is machine drafted, confirmed by a trained annotator, checked again by an independent reviewer, and shipped with overlay previews and a checksum manifest tied to your exact files.
When you train on custom data, you need proof. Not a promise of quality. Proof you can open, scan, and verify.
That is what this post covers. How each label gets made, how it gets checked, and what you receive so you can confirm it yourself.
Who decides the final label: the model or the human?
We use models to move fast on the first pass. Transcription, bounding boxes, segmentation, event marking. The draft arrives in minutes.
A trained annotator then reviews every item, corrects it, and confirms it. That human decision is the label. You never receive raw model output as final.
If your guidelines change, you update the instructions once. The team applies the new rule across your set the same way, and corrections get tracked against the original draft.
Where does independent review catch the costliest errors?
Some errors cost more than others. Boundary calls, ambiguous cases, task rules you wrote for a reason.
A second reviewer checks those files independently. Rework goes back to the annotator with an explanation, not a silent fix. Final labels reflect your interpretation.
You can ask for adjustments before delivery is final, and you can see how each decision maps to your spec.
| Stage | Who | What ships |
|---|---|---|
| Machine draft | Model | Proposals in minutes |
| Annotator correction | Trained annotator | Confirmed labels to your taxonomy |
| Independent review | Second reviewer | Accepted verdict, or rework with reasons |
| Your check | You | Spot-check on previews plus checksum verify |
How do you check quality in minutes?
You should not need to open every annotation file to know if the work is right.
For vision and video, including HD to 4K material, we send overlay previews with labels drawn on frames. You can scan for misaligned boxes, missing instances, or a misunderstood instruction fast.
For speech in English, Hindi, Kannada, Telugu, Tamil, Malayalam, Marathi, and Sanskrit, plus more on request, you get transcripts aligned to audio segments. Flag an issue directly on the segment and we fix it.
What proves nothing changed in transit?
Every delivery ships with a manifest. It lists each file, its checksum, its metadata, and its annotation status.
It covers all modalities in your pack. RGB, depth, LiDAR, sensor and radar streams, and multimodal sets where they apply. Compare checksums on receipt. If anything is missing or altered in transit, you know right away.
What you approved is what you received. Trace any label back to its source file and its review path.
Exhibits from our collection
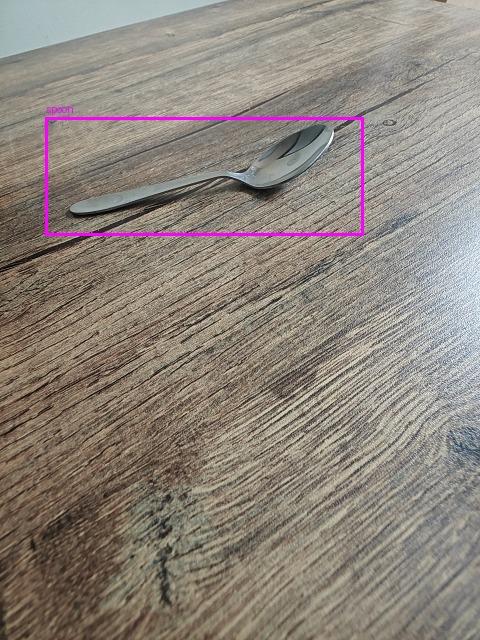
One box from the matching annotation file, shipped alongside the preview above:
{"id": 4852, "label_id": 1, "type": "rectangle", "frame": 0,
 "source": "manual", "occluded": false,
 "points": [239.39, 41.89, 288.73, 104.98]}
Start small and verify it yourself
Start with a paid pilot and put this process to work on your own data. Both sides evaluate fit before scaling.
Questions buyers ask
Do we ever receive raw model output as final? No. The human decision is the label. Drafts accelerate the work; nothing ships on a model score.
What happens when our guidelines change mid-program? You update the instructions once. The team applies the new rule uniformly, and corrections track against the original draft.
How do we raise an issue on a batch? Flag it directly on the preview segment or transcript. Fixes land against the same references you flagged.
Request a pilot and Talk to us
Related reads
Pair with video annotation you can review, text annotation to your taxonomy, and semi-automated annotation.
Sources
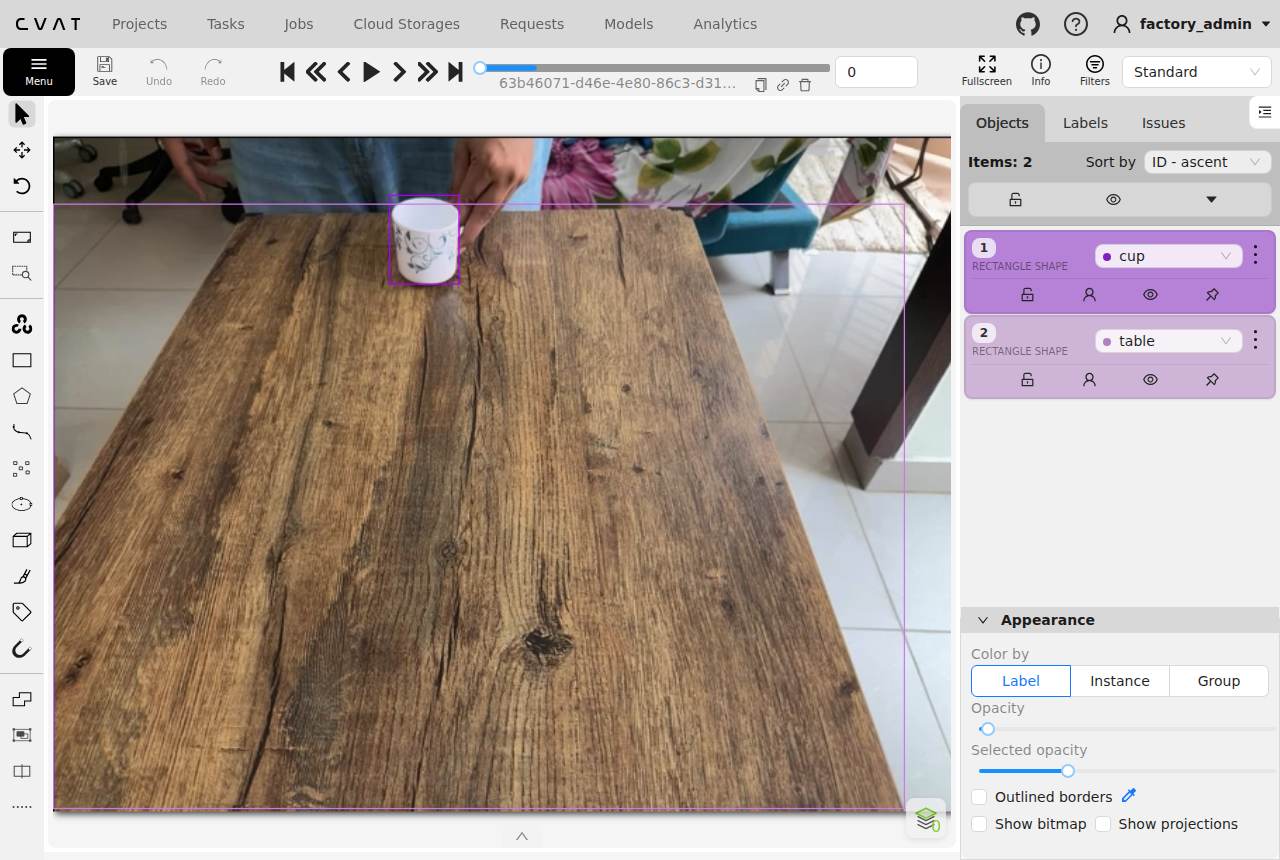
- CVAT documentation — the visual annotation tool in the exhibits above.
- Label Studio pre-annotations guide — how model drafts arrive in the labeling tool for human correction.
- NIST FIPS 180-4, Secure Hash Standard — the SHA-256 behind the per-file checksums in our manifests.
- First-hand: process claims above describe our own pipeline. The exhibits are verbatim outputs — a real CVAT job screenshot and a real annotation record — not illustrations.
Start with a paid pilot and put this process to work on your own data. Both sides evaluate fit before scaling.