02 / Data
Every modality,
to your brief.
Multimodal AI training data — consented, annotated, quality-gated, and delivered with per-file provenance.
01▶
Video
Task-based videos, first-person and egocentric POV, fixed camera, multi-environment shoots. Resolutions from HD to 4K, frame rates to your brief, with bounding-box and action annotation.
02◫
Image
Every category of 2D image collection — objects, scenes, documents to your specification — at whatever resolution and volume your brief demands, with annotation and preview.
03≋
Speech and audio
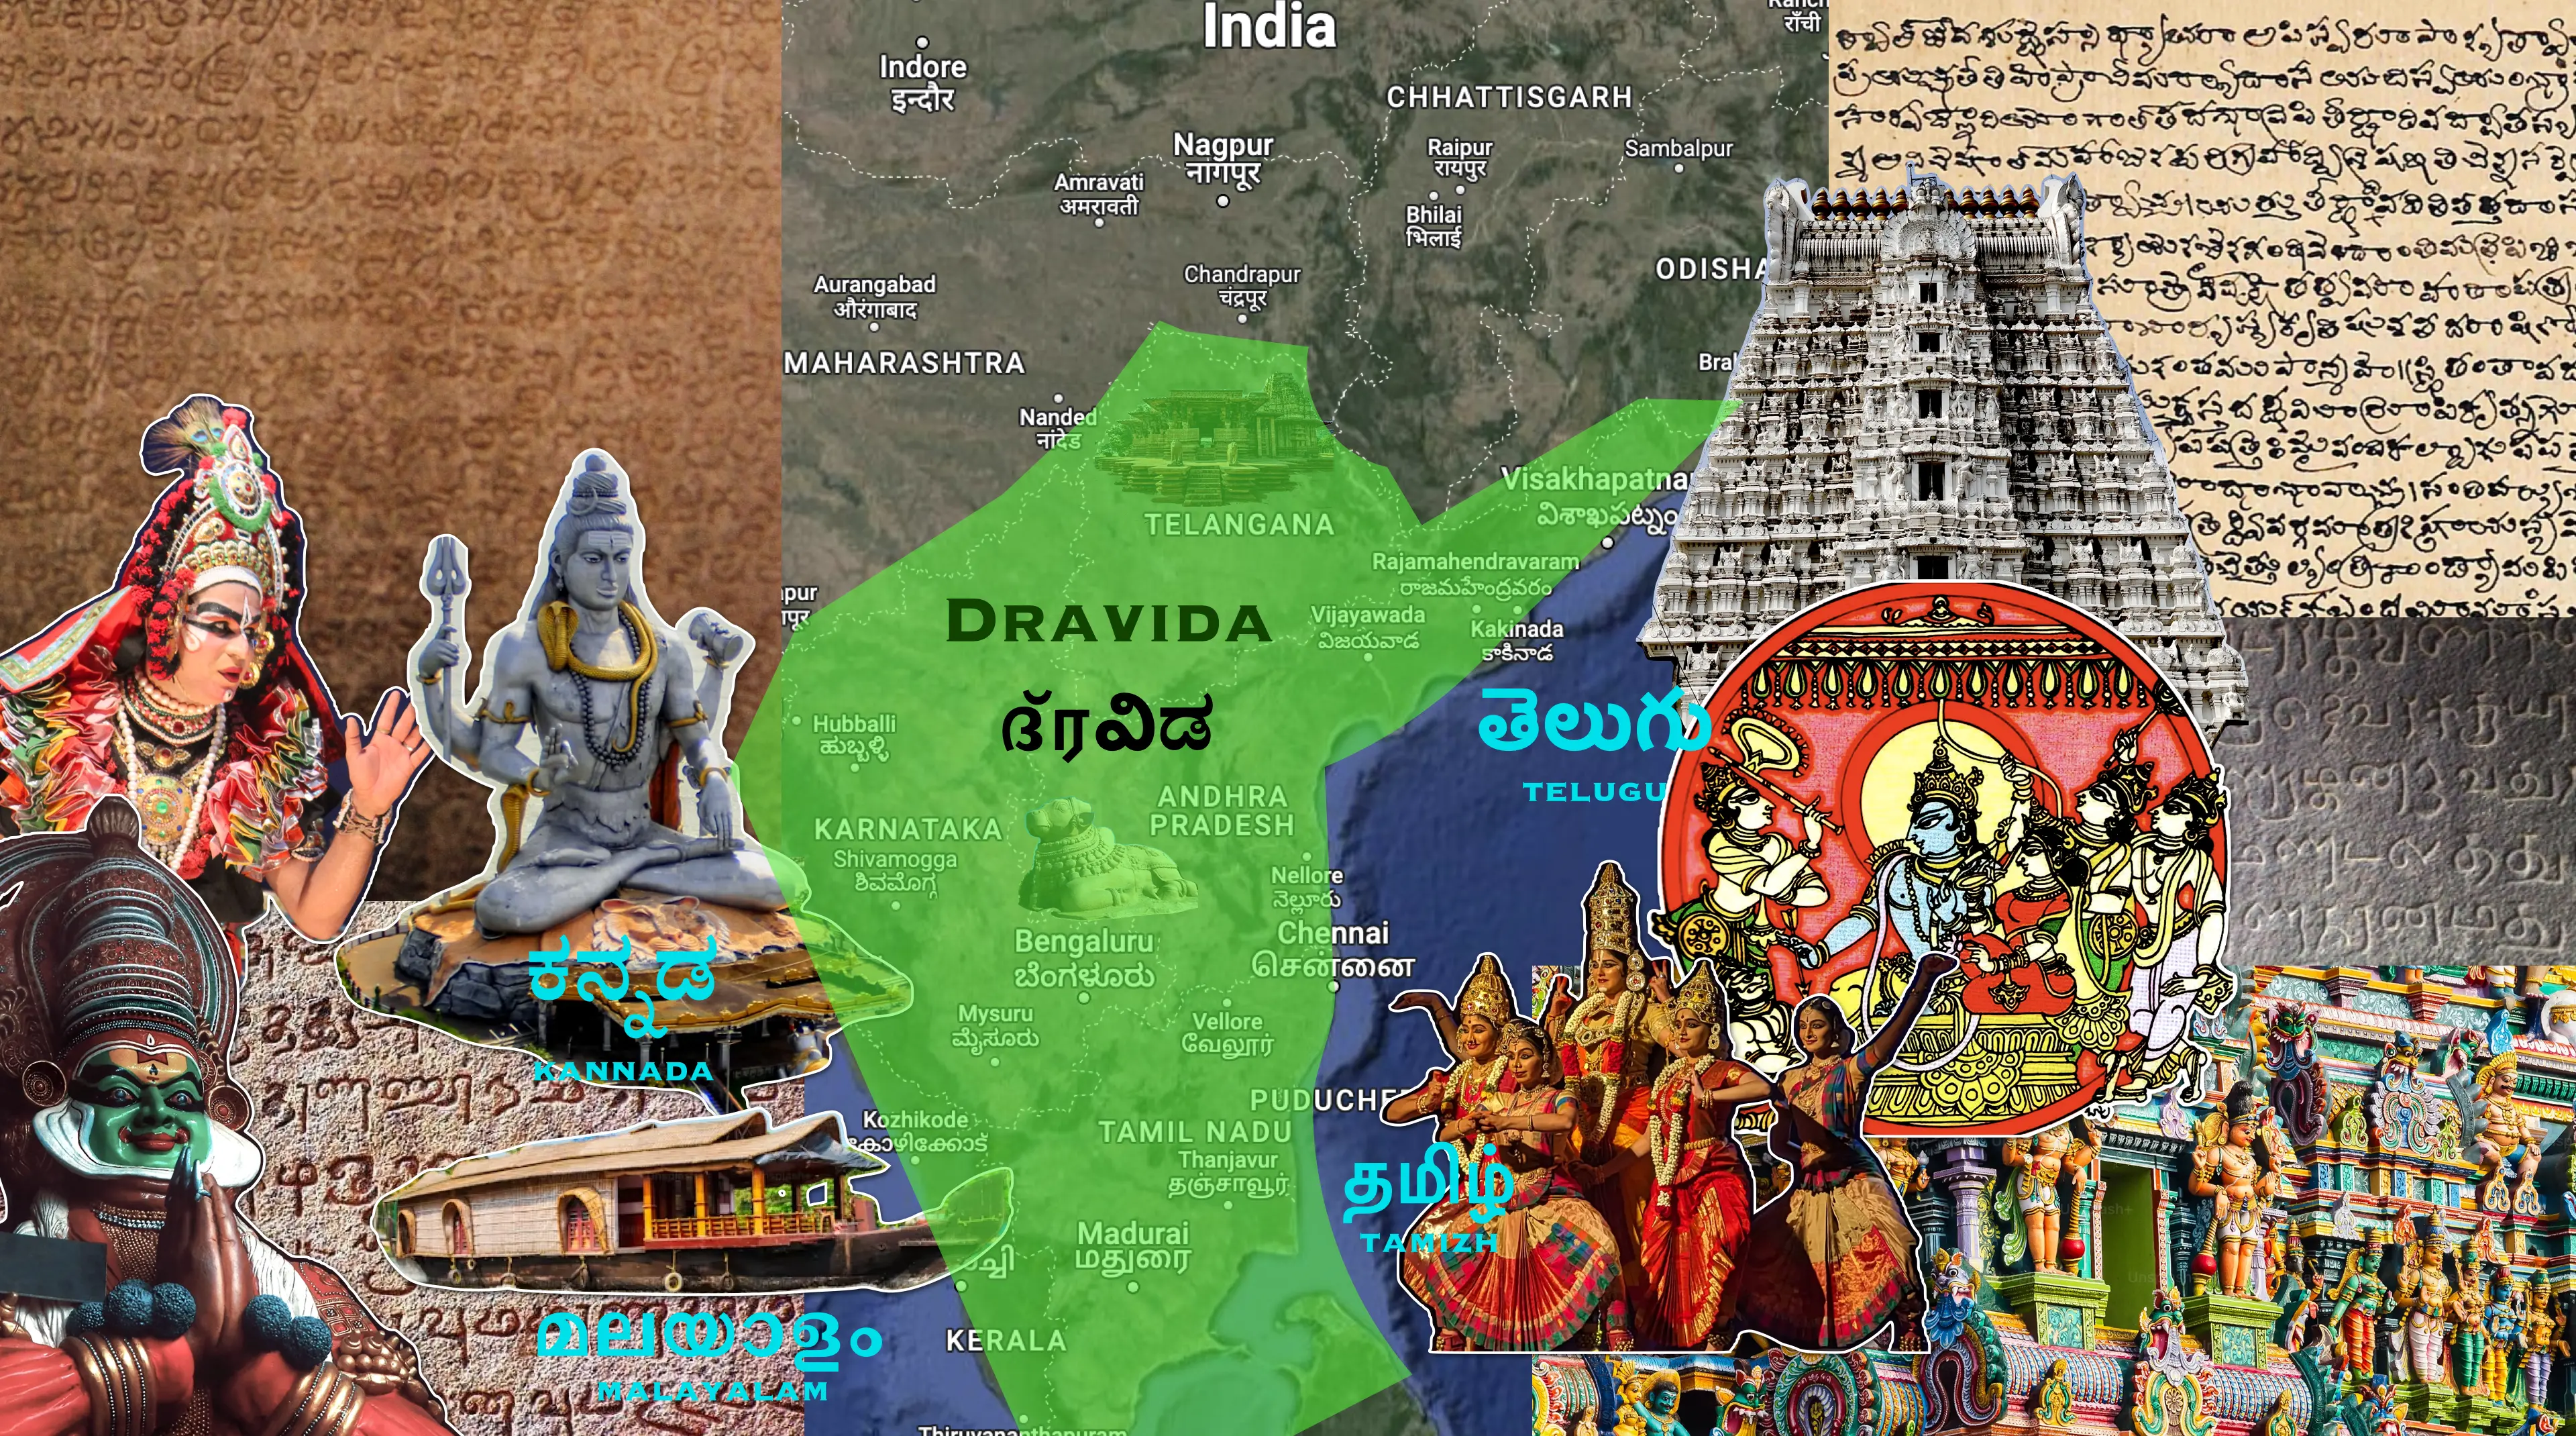
Multilingual speech across 8 languages — English, Hindi, Kannada, Telugu, Tamil, Malayalam, Marathi, Sanskrit — scripted, natural, IVR, studio and field, with transcription to your schema.
04≡
Text
Translation and localization pairs, transcription, named entities, sentiment, content, and moderation annotation to your taxonomy, in every language above and more on request.
05 / FEATURED⁂
Depth and LiDAR
RGB-D captures pairing each video with a synced depth stream, 3D point clouds with per-point range and angles, 3D bounding-box and point-cloud segmentation to your taxonomy.
06 / FEATURED◎
Sensors and radar
Motion-signature captures pairing each video with a sensor recording of the same task — including tactile and force-torque streams for contact-rich work.
07 / FEATURED⬣
Multimodal packs
Everything above, in one delivery. Video, audio, depth, and annotation from the same capture, packed under a single manifest. Raw files never overwritten.
08 / FEATURED⚙
Robot action data
Task demonstrations collected by teleoperation — joint states, end-effector poses, gripper actions, and proprioception, timestamp-synced with multi-view video. LeRobot or HDF5.
09⛟
Driving and on-road
On-road and driving footage captured to your brief — forward-facing, cabin, and multi-camera vehicle setups across real traffic, road types, weather, and lighting, with optional timestamp-synced telemetry. Annotated to your schema under one manifest.

 Godavari
 Dravida Llama
 Godavari Vision